Pattern · seen in 1 breakdown across 1 company

Known-Answer Testing

Catch a component that is silently returning wrong answers by testing it with inputs whose correct answers are known, and treating any mismatch as the failure it will never report itself.

The mechanism

At its core: some components fail silently, returning wrong answers while every health check says they are fine. A known-answer test catches them by asking questions whose answers are already known - the moment a reply does not match, you have found the fault.

LIVE ARTIFACTTEST IF IT'S RIGHTOPEN FULL SCREEN →
THE IDEAMost monitoring assumes a broken component will say so - throw an error, fail a check, stop responding. But some faults are silent: a defective chip or a corrupted byte makes the component return a wrong answer with total confidence, and every health check still reads green. Known-answer testing gets around this by not trusting the component's word. You test it with inputs whose correct answers are known, and a single wrong reply gives the fault away. In practice you run two kinds of tests: quick ones that run all the time alongside real work to catch most faults fast, and long, thorough ones run while the component is offline for maintenance, to catch the faults the quick tests miss. Neither test alone is enough.
WHAT TO TRYBreak the chip with no tests mixed in: wrong answers start reaching users while the health check stays green, and nothing flags them. Then slide in some known-answer tests - soon one comes back wrong and the chip is caught. More tests catch it sooner, but cost more work.

The health check says the server is fine while it quietly returns wrong answers - a known-answer test asks a question it can't fake.

Definition

Some failures leave no trace. A chip with a defect, a corrupted patch of storage, or mis-built code can keep running and answering as if all is well, while quietly returning wrong answers. There is no error, no log line, no failed health check, because the component does not know it is broken. You cannot wait for a signal that will never come. So you create one: test the component with inputs whose correct answers are known, and treat any wrong answer as the failure. You check whether it is right, instead of trusting it to tell you it is fine.
UP, BUT STILL WRONG
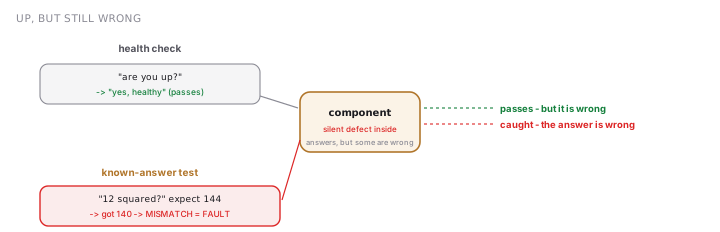
Left, a health check passes on a faulty component; right, a known-answer test catches its wrong result.
A health check asks 'are you up?' and a silently faulty component answers yes; a known-answer test asks 'are you right?' by sending inputs with known answers, so a wrong result gives it away.

This is a different question from the usual one. A health check asks 'are you up?' and a silently faulty component happily answers yes; a known-answer test asks 'are you right?', which it cannot fake. It is also different from independent observability. That pattern makes sure your monitor survives an outage, so it can still see the errors and alerts the system gives off. Known-answer testing is for the opposite case: the faulty component gives off no errors or alerts at all, so there is nothing to see - you have to create the evidence yourself.

In practice you run two kinds of tests, because neither alone is enough:

  • quick and constant - small checks that run all the time, right beside live work, to catch most faults within seconds
  • thorough and occasional - long, careful checks run while the component is offline for maintenance, to catch the faults which quick checks miss

Each kind catches faults the other misses. Run only the quick tests and some faults are never found; run only the thorough ones and faults are found late, after they have already done damage.

When it applies

01The failure corrupts the output but raises no error. A faulty chip, corrupted storage, bad memory, or mis-built code can return answers that look perfectly reasonable but are wrong - and nothing flags them.
02The thing you doubt is whether the answers are correct. When a component's own 'I'm healthy' report tells you nothing about whether its computation or storage is actually right, you have to check the work directly.
03You run so many machines that rare defects become certain. Across thousands of servers, a one-in-a-million fault happens all the time, and every hour it goes uncaught it corrupts or spreads more bad data - so catching it fast is worth a lot.

Tradeoffs

Almost every test checks something that is fine: you run billions of them against healthy hardware just to catch the rare broken one, and that constant overhead has to be justified over and over.
You only catch the faults your tests happen to trigger: some defects show up only for certain inputs, so if no test ever uses that input, the fault stays hidden. The set of tests needs regular updating to keep up.
Tests that run in production are a permanent cost: they take up room next to real work, risk leaving stray settings behind, and need controls to stay out of the way - all of which you have to maintain forever.

The same move, 1 ways

Every row is a production system that bet on this pattern — the note says how, in that system's own terms.

Meta
Engineering at Meta
2022
When a failure leaves no signal to observe, you detect it by asking questions whose answers you already know: give the chip a known input, check for the known output, and treat any mismatch as the detection. This article shows the pattern used at two depths, and the point is that you need both. A shallow, constant version runs beside live work (milliseconds, always on) to find most faults fast; a deep, occasional version runs during maintenance (minutes, invasive) to find the ones nothing else catches. Meta's coverage numbers are the proof that neither depth can stand in for the other. Read the breakdown →

Problems this pattern answers

The walls where its breakdowns live — each opens the cross-company comparison.