Pattern · seen in 2 breakdowns across 2 companies

Master-Only Reads

Send every read to the primary database, never to a replica (a copy that lags behind it), so no read is ever stale - replicas exist only for failover and backups.

The mechanism

At its core: a replica lags the primary, so a read from it can be stale - and for data that drives a decision, like whether a payment already happened, stale means wrong. Send every such read to the primary and the staleness bug simply cannot happen.

LIVE ARTIFACTREAD THE PRIMARY, ALWAYSOPEN FULL SCREEN →
THE IDEAA replica is a copy of the database that lags a little behind the primary. Reading from it spreads read load, which is usually fine - but the data can be a few seconds out of date. For something you only show on a screen, that is fine. For data that decides what the system does next, it is not. The classic case: a payment is recorded on the primary, a retry checks a replica that has not caught up, sees no record, and charges again. Master-only reads send every read to the primary, so no read is ever stale. The cost is that reads no longer scale by adding replicas, so you scale by sharding the primary instead, and the replicas are kept only for failover.
WHAT TO TRYRead from the replica and run the retry check during the lag window - it misses the just-written record and double-charges. Switch to reading the primary and the same check always sees the record, so it charges once.

A retry reads a lagging replica, sees no charge, and charges again - read the primary instead and it never happens.

Definition

Send every read your production system makes to the primary database - the one that takes writes - and never to a replica. A replica is a copy that lags a little behind the primary, so reading one can hand back data that is slightly out of date. If no part of your application ever reads a replica, that staleness can never cause a bug. The replicas still exist, but only for failover, backups, and offline exports - never to serve live traffic.
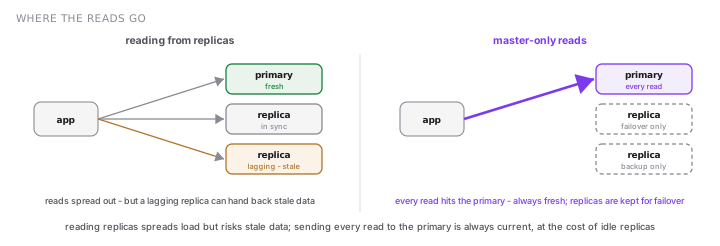
WHERE THE READS GO
Left, reads spread across primary and replicas, one possibly stale; right, all reads hit the primary, replicas idle.
Reading from replicas spreads the load but a lagging replica can return stale data; master-only reads send every read to the primary, so reads are always current and the replicas sit idle, kept only for failover.

This matters most for reads that drive a decision, not just a display. Some data exists only to control what the system does next, such as:

  • has this payment already been charged?
  • does another process already hold this lock or lease?
  • has this exact message already been processed?
  • is this username, seat, or order id already taken?
  • is there enough balance to allow this withdrawal?

Read any of these from a lagging replica and you can get the wrong answer - the idempotency record that was just written looks absent, so the payment runs a second time. The very state that exists to prevent a mistake, read stale, causes it.

The usual reason to read from replicas is to spread read load, accepting a little staleness as the price. Master-only reads refuse that trade for correctness-critical data, and get the lost read capacity back a different way - usually by sharding the primary, which is why the two moves tend to go together. Keep this rule where staleness would change a decision; where a read only feeds a display, a slightly stale replica is fine.

When it applies

01The read decides an action, not just what to show. For state like idempotency records, locks, or dedupe records, a stale read causes a wrong action - a double charge, a lost lock - not just a slightly old page.
02The primary is already sharded, so its load is manageable. When the data is split across many primaries and no single one is overloaded, you do not need replicas to take read traffic off them.
03Lag bugs have already burned you and are hard to catch. When stale-read bugs show up rarely and take forever to diagnose, and the team would rather spend on hardware than chase them, banning replica reads outright is worth it.

Tradeoffs

Read capacity is capped at the primary: since reads never touch a replica, the only way to serve more reads is to split into more shards or buy bigger machines, not to add replicas.
Your replicas cost money but serve no traffic. They are real machines you pay for that sit idle on a normal day, there only to take over if the primary fails or to hold a backup.
Reads that could live with stale data pay full price too. Analytics, dashboards, and feeds do not need fresh data, but under a blanket rule they hit the primary anyway - unless you carve out a separate path just for them.

The same move, 2 ways

Every row is a production system that bet on this pattern — the note says how, in that system's own terms.

Airbnb
Airbnb Engineering
2019
Airbnb reaches this rule through the sharpest possible failure. If the idempotency tables are read from a replica (a copy that trails slightly behind the authoritative master), a correct retry can turn into a double charge: the payment succeeded and was recorded on master, but the retry reads a replica that hasn't caught up, sees no record, and runs the payment again. A few seconds of lag equals a double charge. So Orpheus reads and writes only on master, and wins back the lost scale by sharding on the idempotency key. Pinterest arrives at the same rule from a different angle: replicas are for surviving disaster, not for serving reads. Read the breakdown →
Pinterest
Pinterest Engineering Blog
2015
The other system in this collection with the same rule is Airbnb's Orpheus. Pinterest states it as operational law: standbys lag, lag breeds strange caching bugs, and production never reads from a standby. Airbnb reaches the same rule from a sharper wound, where reading a lagged replica turns a correct, safe-to-repeat retry into a double charge. Same conclusion from two directions: replicas are for disaster, not for reads. Read the breakdown →

Problems this pattern answers

The walls where its breakdowns live — each opens the cross-company comparison.