Committed Nowhere: Reddit's Pi-Day Outage
Breakdown by Akhil Vij · About →
Reddit was down for 314 minutes on Pi Day 2023 (March 14), and the cause was configuration that existed nowhere. It was set up years earlier by a team that no longer existed, manually edited through a third-party tool, saved in no repository, and keyed to a label on the servers that a later Kubernetes upgrade deleted. Two minutes into a routine upgrade of the cluster running Old Reddit, the company's most critical legacy system, the site stopped. Responders were nearly blind: the cluster's own metrics died with it, and only the logs survived. Kubernetes has no way to downgrade, so rolling back meant the thing everyone fears: restoring it from a backup, using a guide written long ago for different software, never tried in production, and rewritten on the fly. The postmortem points past the label bug to the real cause: a fleet of clusters each built by hand and all a little different. The fix is a discipline: standardize everything and document it, so no critical setup ever again lives only in a running system and people's memories.
Run the incident from the operator's seat. Watch every metric die two minutes in, burn through four fix-forward attempts that each change nothing, and make the restore call against a runbook written for software you no longer run. Walk into the same-server trap, then bring traffic back: jump to 100% and learn what cold caches do, or walk the eight steps home. Then read the two-second log clue and the config that took Reddit down.
Problem
The cluster in question ran the Legacy stack, Old Reddit. The company adopted Kubernetes early and built up a collection of one-off clusters, assembled by hand with the kubeadm tool rather than from any standard template, some too big for cloud-managed services to even support. Each cluster was treated as a unique machine to be tended rather than one of many identical ones, with an inconsistent upgrade schedule and configuration that differed from cluster to cluster. The Compute team's upgrade process was genuinely careful: each version was tested against dedicated clusters, then rolled out from the least critical cluster to the most. The team had literally just finished the postmortem for a previous, mildly bad upgrade of this same cluster, whose cause was fully resolved. The engineer started the 1.23-to-1.24 upgrade just after 19:00 UTC. Everything looked fine for about two minutes. Then the site came to a screeching halt.
Responders were on a call within three minutes, and nearly blind: the cluster had lost all its metrics (the edge CDN's stats survived only because they were kept separate on purpose). DNS gave one strange clue. Names inside the cluster, and names in Consul (the service Reddit uses for dynamic DNS across environments), would not resolve, while public DNS worked fine. Pods took extraordinarily long to start and stop; container images under 100MB took minutes to pull over multi-gigabit links; the control-plane logs poured out with no obvious error. Calico, the cluster's networking layer that gives every pod its network connection and routes, was unhealthy. The fix-forward attempts read like a checklist of reasonable moves that changed nothing:
- a stuck pod matched a known minor bug in the container runtime (deleted, but not the problem)
- the pods for Calico's aggregation proxy were deleted, and then simply never came back
- a rolling restart of the control plane, with no change
- the full off-and-on-again, with no change
- and one real finding: the timeouts were coming not from the writes but from the cluster's admission checks, the policy step that approves each change, so deleting those configs made the timeouts vanish at once
The cluster stayed dead.
Rolling back was Plan A from the first minutes, and Reddit delivers the industry-wide bad news plainly: Kubernetes has no supported way to downgrade. An upgrade automatically migrates the cluster's stored data to the new version, and there is no reverse path. A downgrade means restoring from a backup. The backup existed, taken as a matter of routine. The restore was another matter entirely.
Solution
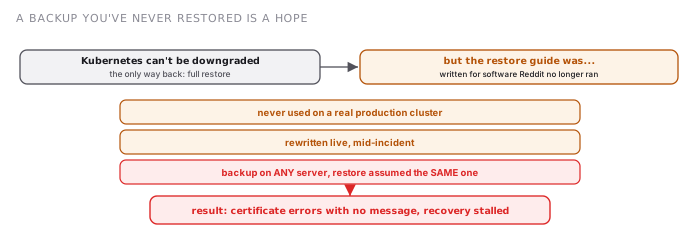
Two hours in, out of constructive ideas, they made the hard call. The worker servers would be wiped by the restore anyway, so all of them were terminated first, twenty minutes of API calls on Reddit's largest cluster. Then a restore began that nobody on the call had ever run, against the company's most important single point of failure. The guide had been written for a long-dead Kubernetes version, and from before Reddit changed the software that runs its containers, so its old commands had to be rewritten on the fly as the team ran it. It also hid a problem the recovery ran straight into. The backup could be taken on any control-plane server, but the restore quietly assumed the same server, a mismatch nobody had ever hit, because the restore had only ever been practiced on small pilot clusters, never in production. They restored onto the guide's designated 'first' server and brought it up as a one-server control plane. The autoscaler sprang to life, which proved the networking was back, so they deliberately switched it off again to keep control. They hit an AWS capacity limit for the control-plane machine type. And then they hit the trap: new control-plane servers got stuck joining, with no error, unable to reach etcd (the cluster's shared source of truth) on the restored server, because the security certificates it presented carried the wrong hostname. A small group found it in minutes, the certificates were regenerated with some fumbling and no documentation, and the control plane was whole again.
Bringing traffic back was its own discipline, because Reddit's caches carry real load, not just speed: jump to 100% at once and a 'thundering herd' of requests slams into services that had gone idle and scaled down during the outage. So they started at 1% and walked up: 5, 10, 20, 35, 55, 80, 100, stopping particularly touchy legacy services by hand and re-enabling them with care. The outage was over. The cause was still unknown.
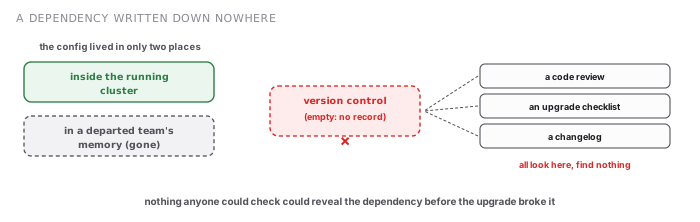
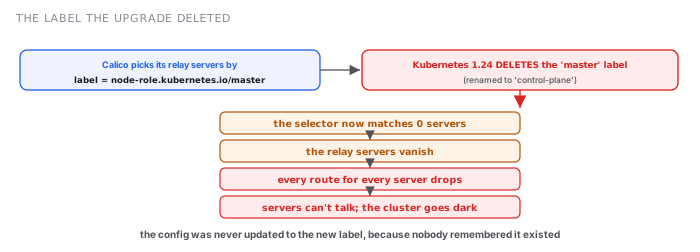
The investigation is the postmortem's best chapter. The metrics had died with the cluster, but the logs survived, because they were low-level and deliberately not tied to Kubernetes: 3.9 billion lines of them. The API server's logging jumped five-fold at 19:04:49, but its only hint was the already-known admission-check timeouts. The Open Policy Agent's own logs stopped five seconds before that, a dead end. Calico's logs held the real clue. Two seconds before the chaos, Calico across the cluster dropped its routes to the first upgraded control-plane server (expected), and then dropped all routes for all servers (not expected). Here is what route reflectors are: in a large cluster, rather than have every server exchange routes with every other server, a few designated servers relay routes for everyone (recommended past 100 servers; Reddit notes it runs far more). Reddit's relays were the control-plane servers, picked by the label node-role.kubernetes.io/master, the label Kubernetes 1.24 removed. The selector matched nothing, the relays disappeared, and networking stopped. And the reason nobody saw it coming: the configuration had been set up years earlier by a departed team, lived only inside Calico's own settings, edited by hand, and was committed nowhere. One engineer happened to remember the feature existed, and proved the mechanism during the postmortem.
The remediation section refuses to stop at the label. Reddit names the real cause as inconsistency: almost every important cluster had been built a little differently. It calls this 'a natural consequence of organic growth, and one which has caused more outages than we can easily track.' The cure is a program:
- standardize and share components instead of one-off configuration;
- build more pre-production clusters that can be tested with confidence;
- build tooling to manage whole clusters so they can be recreated and kept alike;
- codify everything that can be codified, 'both to ensure consistent application and to have a clear historical record of the choices that we've made';
- document in detail whatever cannot be codified;
- and treat every remaining exception as a candidate for replacement.
Tradeoffs
- Critical setup that exists outside any record is a time bomb with no visible clock. The route-reflector configuration was correct for years, and unfindable: no repository, no trail, its authors gone. Nothing in a code review, an upgrade checklist, or a changelog read could surface a dependency that was written down nowhere. The audit this class demands runs on one hard question: what does this system depend on that exists only inside the running system?
- Configuration that lives only in a vendor's tool is a gap someone has to close on purpose. Calico's route-reflector config expects the fetch-by-tool, hand-edit, re-upload cycle, which actively resists being managed as code. The honest options are exactly three: build the custom tooling that brings it into the record, replace the mechanism with one that can be recorded, or accept it as a documented, named exception. Reddit had a fourth state, unrecorded and forgotten, which is the one this outage retired.
- Upgrades with no reverse gear change the math of every decision after them. Because Kubernetes automatically migrates a cluster's data on upgrade, there is no supported downgrade; rolling back means restoring from backup. That single fact stretched the incident: hours of fix-forward attempts were rational precisely because the fallback was feared, never rehearsed in production, and of unknown length. Systems without a cheap way to reverse force their operators to gamble on fixing forward.
- A backup you have never actually restored under pressure is a hope, not a capability, and the sharpest danger is a backup and a restore that do not match each other. The guide predated the container runtime in use, had to be rewritten live mid-incident, and hid the any-server-backup / same-server-restore mismatch that cost a round of certificate failures with no error message. Restore paths need the same rehearsal discipline as upgrade paths, on the real shape of production, before the day they are the only option left.
- The newer parts of Reddit kept working, which points to the real lesson about how far an outage spreads. Reddit's modern service layers stayed up the whole time; the outage reached most user actions anyway, because the legacy cluster is still the most critical thing everything else depends on. Isolation work is only as good as whatever still depends on the thing you isolated. Reddit's own conclusion is to keep shrinking that dependency, not to celebrate the layers that survived.
- Recovery traffic is a workload with its own physics. Idle services scale down, caches go cold, and 100% of normal demand aimed at a cold system is a stampede, not a return to normal. Bringing traffic back from 1% to 100% in eight steps, turning fragile legacy services back on by hand, treats the return of load like a careful rollout. It is the same discipline teams use for a migration, but almost never practice for recovery.
Patterns in this article
- No Uncommitted Config
This comes straight from the main promise in Reddit's fixes: codify everything, 'both to ensure consistent application and to have a clear historical record.' The pattern is that no critical state may exist outside version control. State that can only be managed through a vendor's tool gets custom tooling to bring it into the record, gets replaced by something recordable, or becomes a named, documented exception, never a fourth thing that is simply unrecorded. The record has a second job too: leaving a trail for the responders who arrive after the original authors have gone.
- Rehearsed Restore
This comes from the recovery's hardest lesson. A routine backup was paired with a restore guide written for a long-dead Kubernetes and a retired container runtime, never run against production, and rewritten live during the outage. It also hid the any-server / same-server mismatch that stalled the control plane on certificate errors with no message. Restore is a real capability only if it is rehearsed on the true shape of production, kept current with every environmental change, and consistent with how the backup was actually taken.
- Universal Staged Rollout
Here the pattern shows up in the direction nobody practices: letting traffic back in. Traffic returned at 1% and walked up through eight steps to 100%. Idle, scaled-down services and cold caches were treated as what they are, a system that cannot absorb normal load yet, and touchy legacy services were let back in by hand. It is a staged rollout applied to recovery load rather than to a migration.
- Load-Bearing Cache
Traffic was brought back gradually because Reddit's caches carry real load, not just speed. As Reddit puts it, 'Reddit relies on a lot of caches to operate semi-efficiently,' and full traffic against cold caches produces stampedes in the downstream services that went idle during the outage. Treat a cache's hit rate as capacity, and a cold cache as a system that is not ready for full load yet.
Spotted a mistake? Tell me →
Breakdown by
Akhil Vij
Staff engineer, previously at Agoda and Informatica (Salesforce)
How lessons are made →One real failure every two weeks
Why the companies that faced it chose differently, what each choice cost, and how you’d defend your own design.