Stopping the Cause Didn't Stop the Outage: Slack's 2-22-22
Breakdown by Akhil Vij · About →
On February 22, 2022, Slack was down for hours: many people could not connect. Slack's team stopped the maintenance that had started the outage, and it changed nothing, because by then the system was breaking itself. The maintenance was a routine batched upgrade; each restart briefly dropped cache servers, replaced automatically with empty ones. Two batches had gone fine the week before, but the third ran at peak traffic, when enough of the cache was empty to expose an expensive query it normally hid. One common startup request, looking up who is in your group chats, was cheap only while cached. With the cache empty, it had to search the entire database at once. The overwhelmed database timed out those very requests, so the cache stayed empty and fed itself. Engineers, not the trigger, ended it. They capped how many apps could start at once, protecting connected users and letting the cache refill; when they raised that cap too far, the overload returned, so they climbed back more slowly. Finally they fixed the expensive request.
Roll the Consul upgrade in 25% steps and watch two of them get absorbed, then land the third at peak traffic and cross the tipping point. Pause the rollout and watch it change nothing: the outage now keeps itself going. Throttle new logins to get back under the tipping point, raise the limit too far once to see it relapse, fix the expensive query, and walk the system home in small steps.
Problem
When a Slack app starts a new session, it has to load a lot before anything works: your channel list, your preferences, your recent conversations. That loading leans on two layers:
- underneath, the database (Slack calls its database layer Vitess);
- in front of it, a large cache that holds copies of recently used data, so most requests never reach the database at all.
Two pieces manage that cache. Mcrouter spreads requests across the many cache servers, and a newer piece called Mcrib decides which cache servers are in use at any moment. Mcrib does this by watching Consul, a system that keeps a live list of which machines are up. When a cache server drops off that list, Mcrib swaps in an empty spare. If a server later rejoins, Mcrib empties it first, so it can never hand back data that went stale while it was away.
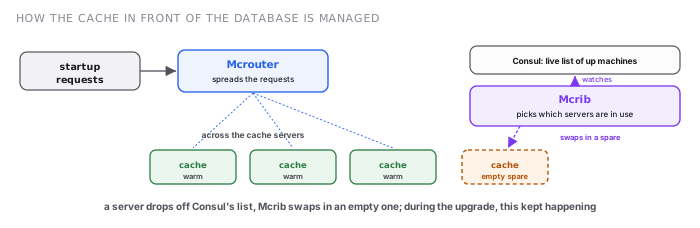
Its designers knew empty cache servers are risky, so the goal was to keep the set of servers stable and wipe one only when necessary, and Mcrib was genuinely better at this than the older system it replaced.
The week's maintenance was an upgrade to Consul itself, rolled out to 25% of the machines at a time, with the restarts kept slow and one at a time to avoid disturbing anything. While a machine restarts, it drops off Consul's live list and then rejoins. So from Mcrib's point of view, cache servers kept briefly 'dying,' and Mcrib kept dutifully replacing them with empty ones. Two of these 25% rounds had finished the prior week without incident. The third ran on February 22 and crossed a tipping point as the day hit peak traffic: enough of the cache was empty at exactly the moment demand was highest.
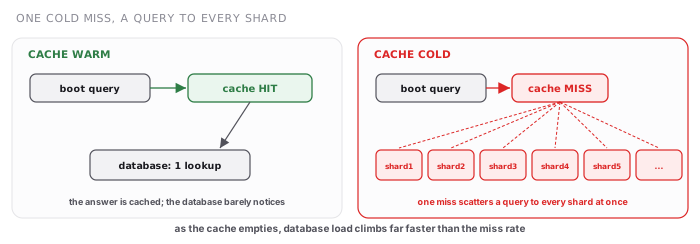
The danger was hidden in how one kind of data was stored. When the app starts, it asks which people are in your group direct messages, and that membership data was stored in a table split up by user. Splitting by user is efficient for finding a user's channels, but it is the wrong way around for finding a channel's members. To answer the backwards question, the database has to check every split (each split is called a 'shard') at once. Normally that was invisible, because the answer never changes and so stays in the cache for a long time, almost never reaching the database. But with the cache partly empty, nearly every starting app forced a query against every shard, and database load climbed far faster than the share of requests that missed the cache, until more and more of those queries timed out. Those timeouts were what sealed the loop: a query that times out never fills the cache, and an empty cache guarantees the next miss.
Solution
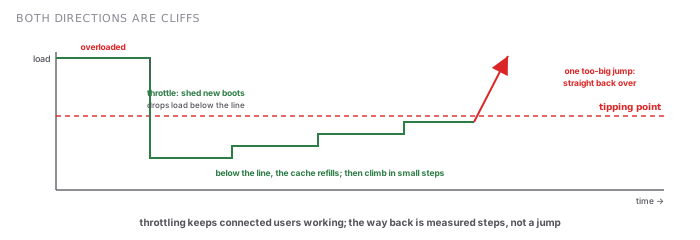
The response ran on two tracks: understand the load, and reduce it. The reduction is a study in shedding load under pressure. The team specifically limited how many apps could start up, and they knew exactly what that meant. Users not yet connected would stay out, so users already connected kept working, and the lighter query load would let the cache start filling. The first, restrictive limit worked. Easing that limit for the first time taught the other hard lesson of this class. They raised the limit too far, database load shot past what it could handle again, failures climbed, and they had to drop back down and climb in smaller steps. Near a tipping point, the safe way back to full traffic is small steps, watching the useful work getting through at every one.
The trap itself was fixed in place. The expensive query was changed to fetch from the database only the entries actually missing from the cache, instead of re-fetching everything on any miss. And because this membership data never changes, so a slightly old copy is fine, the query was also allowed to read from the database's read-only copies, not just the main copy, which multiplied the capacity available to serve it. With the trap weakened and traffic held below the tipping point, the loop ran in reverse: the cache filled, hit rates rose, and database load fell. The cap on new startups was then raised back to normal in steps, keeping useful work high, until service was fully restored.
The lessons are the best part of the write-up. The upgrade had been paused early, and it changed nothing. Slack looks closely at Mcrib, and does not pin the outage on it. It contributed 'not by being incorrect or inefficient, quite the opposite': it detected and replaced dropped cache servers faster than the old system ever could, and that very speed amplified the churn. In Slack's words, it is 'objectively a better system, but its efficiency made the broader system behave in a less safe way.' The expensive query was permanently moved to a table split up by channel instead, and the rest of the queries that sit behind a cache were audited for the same shape of risk. Slack also noted that a brief network outage hitting the cache servers could set off the same cascade, and is changing how Mcrib works to guard against it. Nolan closes with Richard Cook's 'How Complex Systems Fail': complex systems always carry latent flaws, each harmless on its own, waiting for the combination. And Slack publishes these, she writes, so the rest of the industry can learn from their worst Tuesday.
Tradeoffs
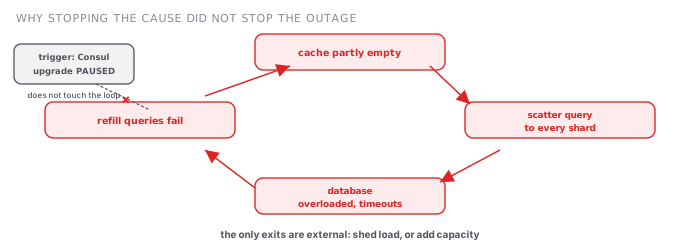
- The defining property of this failure class is that removing the cause does not help. Pausing the Consul rollout early was the correct move and accomplished nothing, because the system had crossed into a state that regenerates itself. An empty cache drives database overload, the overload times out the refill queries, and the still-empty cache drives the next round. Response plans built around 'find the trigger and stop it' are not enough here. The trigger is already in the past; the loop is the thing you have to break.
- A cache that makes your traffic servable is capacity, not just an optimization, and its warmth is a hard dependency. Slack's database could not serve the startup traffic once the cache lost a realistic share of its hits; the system's real capacity assumed the cache was full. Systems in this position need to treat a full cache like any other planned, budgeted resource: protected during maintenance, warmed before serving, and monitored as closely as any other critical part of the system.
- Better automation can make the system worse without being wrong. Mcrib replaced departed cache nodes faster and more correctly than its predecessor, and that speed turned a slow rolling restart into cache servers being emptied and replaced very fast. Repair speed is not free: every automatic 'repair' that costs the system something (an emptied cache server, a wipe, a failover) needs to be paced or budgeted, or held back until it is certain, otherwise its very speed makes things worse in exactly the situation it was built for.
- Data layouts carry hidden amplifiers that only fire when the cache goes cold. The expensive query was invisible for as long as the cache absorbed it: data that never changes, kept for a long time, near-perfect hit rates. It turned each cache miss into a query against every shard the moment the cache went cold. The audit that matters is the one Slack ran afterward: find every high-volume query whose cost is only acceptable because a cache is currently hiding it.
- Escaping a self-sustaining failure means shedding load below the tipping point, and shedding is choosing. Throttling client boots was a priority decision stated plainly: not-yet-connected users were kept out so connected users kept working and the cache could refill. The return trip has its own discipline: raising the limit too far in one step brought the outage back, while small steps, watching useful throughput at each one, got them home. Near a tipping point, both directions are dangerous: shed too little and you stay down, restore too fast and you relapse.
- Retries contributed even though they were done right. Slack's apps wait longer and longer between tries, plus a random extra bit (the textbook discipline), and the postmortem still lists automated retries among the loads that fed the failure. The reason: a client cannot tell a brief local glitch (retry right away) from global overload (ideally, go quiet). Correct behavior in each client summed to harmful behavior across the fleet. The honest conclusion is that careful retry behavior in each client reduces what retries add to a pileup, but cannot remove it.
Patterns in this article
- Load-Bearing Cache
Slack's database tier could not serve the startup traffic without the cache absorbing most of it. The cache was really planned capacity dressed up as a mere optimization, and its warmth was a hard dependency that the maintenance churned away. The pattern names the discipline for systems in that position: treat the hit rate as capacity, protect warmth during maintenance, and warm a cache before promoting it. It also means auditing for queries whose cost is only survivable while the cache is hiding it.
- Conservative Auto-Remediation
Here the pattern shows up by its absence. Mcrib replaced dropped cache servers faster and more correctly than the system it replaced, and Slack's own verdict is exact: 'its efficiency made the broader system behave in a less safe way.' Every automatic repair that costs something (an emptied cache server, a wipe) needs pacing or a budget, and Slack's follow-up changes to the Mcrib control loop add exactly that restraint.
- Priority-Aware Load Shedding
Here the pattern shows up during the incident, not in the design. The client-boot throttle was an explicit priority call: users without a booted client were kept out so connected users kept working and the refill queries could land. Then came the return-trip discipline the class demands: raising the limit too far in one step brought the outage back, and small steps, watching useful throughput at each one, restored full service.
Spotted a mistake? Tell me →
Breakdown by
Akhil Vij
Staff engineer, previously at Agoda and Informatica (Salesforce)
How lessons are made →One real failure every two weeks
Why the companies that faced it chose differently, what each choice cost, and how you’d defend your own design.