Pattern · seen in 3 breakdowns across 3 companies

Independent Observability

Watch a system from a separate, independent path that shares as little as possible with it, so that whatever takes the system down cannot take down the monitoring with it.

The mechanism

At its core: if your monitor runs on the same system it watches, then whatever takes the system down takes the monitor down too - and you go blind at the worst moment. An independent watcher, sitting outside on separate infrastructure, survives the outage and can still tell you the system is down.

LIVE ARTIFACTDON'T SHARE ITS FATEOPEN FULL SCREEN →
THE IDEAA monitor is itself a system that can fail. If it runs on the same infrastructure as the thing it watches, they share fate: the outage that takes down the system takes down the monitor too, so no alert fires at the exact moment you need one. This is a circular dependency - the watcher secretly depends on the thing it is supposed to watch. Independent observability breaks the loop by moving the watcher into a separate failure domain, ideally a dumb prober outside the walls that just uses the public interface like a customer. It cannot tell you much - only that the system is down - but it can tell you that within minutes, even when your detailed built-in monitoring has failed along with the system.
WHAT TO TRYPut the monitor on the platform and trigger an outage - it dies with the platform and no alert fires, so you are blind. Move it to an independent watcher outside and trigger the same outage; the watcher survives and the alert fires within minutes.

When the outage takes down your monitor along with the system, you go blind - unless the watcher lives somewhere the outage cannot reach.

Definition

Watch the system from an independent path that shares as little as possible with it - separate machines, separate dependencies, even separate assumptions - so the failure you are trying to catch cannot knock out the thing catching it. The strongest version is deliberately dumb: a watcher sitting outside the walls that just uses the system's public interface the way a customer would, knowing nothing about how it is built. It has one job - to tell you THAT the system is down, within minutes - because every part the watcher shares with the system is a way for the system's failure to reach the watcher.

This pattern is really about escaping a trap called a circular dependency. That is when system A watches or controls system B but also needs B to work. In normal times you never notice; the moment B fails, A fails with it - and loses the ability to see or fix the problem at the exact moment it matters. The same loop hides in many places:

  • a deploy system that runs on the very services it deploys
  • a secret store whose own secrets are kept inside itself
  • DNS that needs DNS to find its own upstream
  • a certificate authority whose renewals depend on the services those certificates protect

So the discipline is to map every dependency of anything with a safety or control job, and check that none of them wires back to the system it is protecting. That map is usually surprising, because modern infrastructure shares so much underneath - control planes, identity, DNS, metrics - that these hidden loops are almost always there.
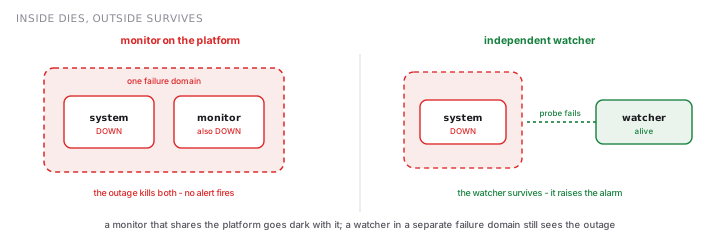
INSIDE DIES, OUTSIDE SURVIVES
Left, a monitor inside the platform dies with it, no alert; right, an outside watcher survives and alerts.
A monitor inside the platform's failure domain dies with it, so no alert fires when it matters most; a watcher in a separate failure domain survives the outage and can still raise the alarm.

Breaking such a loop means moving the watcher into a different failure domain - separate infrastructure, a separate region, a separate provider, or something primitive enough to share nothing at all. In practice you keep two layers: the detailed, built-in monitoring that helps you diagnose problems on a normal day, and a simple independent watcher whose only job is to catch the rare total outage that takes the built-in monitoring down too. This differs from a dead man's switch, which watches for a heartbeat going silent; here the watcher actively probes from outside, and its independence - not how it checks - is the part that matters.

When it applies

01Your monitoring runs on the very platform it watches. When the alerting or paging lives on the same system it is meant to watch - worst of all, a monitoring product watching itself - an outage takes out both at once.
02A total outage has to be caught within minutes. When the whole system can go down and its own telemetry goes down with it, you need something outside to notice fast.
03Your repair automation checks health on the thing it is repairing. When the automation that fixes a system runs its checks on that same system, a failure there blinds the very thing meant to recover it.
04The alerts did not fire, or you could not ship a fix. When an incident review turns up that the alerts never fired or the fix could not be deployed, there is almost always a hidden loop underneath - the tool depended on the thing that was down.
05You are building something that guards credentials. For a secret store, a certificate authority, or an identity system, the thing that protects the credentials must not itself need those credentials to run.
06You are adding a dependency to a most-critical system. Before you do, trace whether that new dependency could, through a chain, end up depending on the very system you are protecting.

Tradeoffs

Independence comes at the cost of detail: the outside watcher can tell you that something is wrong, but not why - the deep diagnosis still needs the built-in telemetry that shares the system's fate.
The independent watcher is easy to forget. Because it is simple and almost never fires, it tends to rot - so it needs its own tests, its own paging, and someone who owns it.
Staying independent gets harder over time. As the platform grows, every convenient little integration quietly re-connects the watcher to the thing it watches, so independence has to be actively defended.
Finding the hidden loops is a lot of work. Tracing every dependency to spot a circular one takes either good tooling or a careful, by-hand audit of long chains.
You can never share nothing at all. Some common ground - DNS, internet routing, the cloud's control plane - is unavoidable, so the goal is to cut the dependencies that matter, not to chase perfect isolation.
Cutting too much creates its own mess. Duplicate everything and the architecture gets harder to maintain than the failures it was meant to prevent - how far to go depends on how critical the protected system is.

The same move, 3 ways

Every row is a production system that bet on this pattern — the note says how, in that system's own terms.

Airbnb
Airbnb Engineering
2026
The common thread of the redesign is that no part of a safety mechanism may depend on the thing it protects. Airbnb breaks the loop at three points: dedicated clusters break the compute dependency, a separate network path breaks the data-flow dependency, and an external heartbeat watched from outside Airbnb's own infrastructure breaks the alerting dependency. Each was a hidden loop, invisible in normal operation and dangerous only when it mattered. The lesson is the discipline of mapping every such loop before deliberately cutting it. Read the breakdown →
Datadog
Datadog Engineering Blog
2023
Datadog shows the payoff of an independent observer. A deliberately basic outside watcher, sitting outside the infrastructure and assuming nothing about it, detected a total platform outage in three minutes, while the in-platform alerting died along with the platform. The rule it demonstrates: an independent observer is worth exactly as much as it does not share with the thing it watches, including its assumptions. Read the breakdown →
Roblox
Roblox Blog
2022
The monitoring that would have shown what was wrong ran on Consul, so when Consul went unhealthy the instruments went dark, and the team burned four wrong theories over fifty hours before the flame graphs finally surfaced the real bug. This is a circular dependency: the tool that watches a system must not itself depend on that system, or it fails at the exact moment it is needed. Roblox's first post-outage fix states the rule directly, that the monitoring no longer depends on the systems it watches, and the 73 hours are what its absence cost. Here the lesson was learned the expensive way, from three days in the dark. Read the breakdown →

Often used together

Patterns sharing breakdowns with this one — derived from co-occurrence, threshold ≥2 shared.

Problems this pattern answers

The walls where its breakdowns live — each opens the cross-company comparison.